Skip to content
CTS Field Notes

CTS Field Notes

Overlooked problems, assumptions worth questioning, and things worth knowing.

Practical technology judgment for business leaders. Fresh perspectives for curious minds.

A Faster Model Is Not a Faster Decision

The Department of Energy recently announced GridFM 2.0, a research project intended to help utilities evaluate far more possible grid scenarios, far more quickly. That is a real advance in planning capacity: more contingencies can be tested, more options can be compared, and fewer important cases need to be discarded merely because a model takes too long to run.

But a faster model is not a faster decision.

Every scenario still begins with choices. What demand is assumed? Which failure modes count? What cost, reliability, or service tradeoff is acceptable? A system can make those choices more visible and make their consequences easier to compare. It cannot decide which assumptions the organization is willing to own.

That distinction matters well beyond the grid. A finance model, a security dashboard, or an AI assistant can produce more possibilities than a team could review manually. The useful question is not whether the tool reached an answer. It is whether someone can explain the inputs, the alternatives rejected, and the reason this particular path was chosen.

Good technology expands the decision room. It does not remove the person responsible for the decision.

Permalink

Apple Business, Intune, and RMM: Three Parts of Managing One Device

A new Mac can arrive looking almost finished.

It came from an approved reseller. The employee has a Microsoft 365 account. Someone has access to Apple Business. Someone else has Intune. The IT provider has an RMM platform.

That sounds like a managed device.

It may be. But only if the organization can answer a less glamorous question:

Which system is responsible for what?

Apple’s business offering has recently been renamed Apple Business; it combines capabilities previously associated with Apple Business Manager, Apple Business Essentials, and Apple Business Connect. Apple’s documentation makes the naming change clear. The older “Apple Business Manager” name will remain familiar for a while, and people sometimes call the whole category “Apple device management.”

The important distinction is that Apple Business, Microsoft Intune, and an RMM can all touch the same Apple device—but they solve different problems.
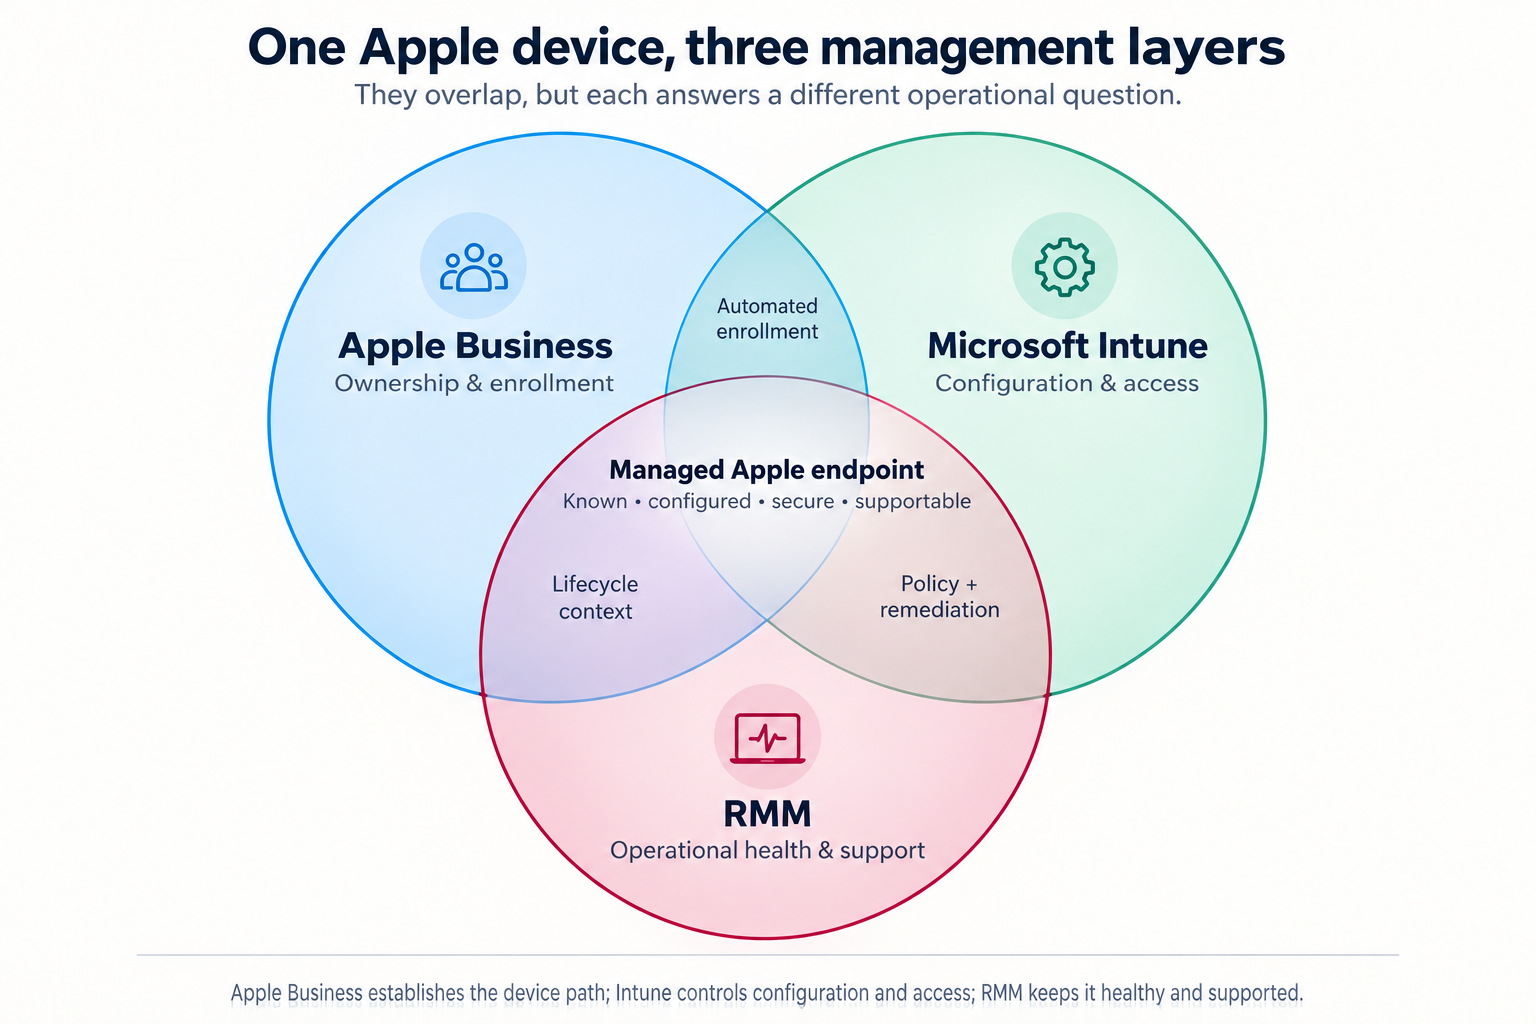
Apple Business, Microsoft Intune, and RMM Venn diagram
The overlaps are conceptual; they do not mean every product has a direct technical integration with every other product.

*The overlaps in this diagram are conceptual. They do not mean every product has a direct technical integration with every other product.*

Apple Business: ownership, identity, and the enrollment path

Apple Business is the Apple-side organizational layer.

Its central role is to help the organization establish that a Mac, iPhone, or iPad is company equipment and direct it into an approved management process. Depending on the organization’s Apple configuration, its functions can include:

  • Assigning eligible devices purchased through Apple or participating resellers
  • Directing devices to a mobile-device-management service through Automated Device Enrollment
  • Managing organization roles and Managed Apple Accounts
  • Acquiring and assigning Apple apps and books
  • Connecting Apple identities with the organization’s identity environment
  • Apple Business answers:

    Does this device belong to the company, and where should it enter management?

    That is essential when a device is first issued, replaced, reassigned, lost, or retired. It reduces the chance that the business discovers too late that a “company Mac” is still effectively tied to a former employee’s personal Apple account.

    Apple Business may include Apple-native management capabilities depending on the subscription and configuration. But in a Microsoft 365-centered environment, it is usually best understood as the Apple ownership and enrollment foundation—not the complete answer to endpoint security or day-to-day support.

    Microsoft Intune: configuration, security, and access

    Microsoft Intune is a cloud endpoint-management service. Microsoft says it can enroll, configure, secure, and update devices; deploy and protect applications; and use compliance status in access decisions. It supports macOS, iOS, and iPadOS alongside Windows and other platforms. Microsoft’s Intune overview explains its connection to Entra ID and Conditional Access.

    For Apple devices, Intune can commonly handle:

  • Device-enrollment profiles and configuration policies
  • Encryption, password, screen-lock, and operating-system requirements
  • Deployment of business applications and settings
  • Compliance reporting
  • Certificates, Wi-Fi, VPN, and security configuration
  • Restrictions on device features or data sharing where appropriate
  • Conditional Access decisions for Microsoft 365 resources
  • Mobile application management for work data on personally owned devices
  • Intune answers:

    What must be true before this device can use company information?

    That question matters most when an employee signs in to Microsoft 365 from a Mac, iPhone, or iPad. Intune can help ensure the device meets the organization’s requirements before it reaches email, SharePoint, Teams, or other business systems.

    RMM: operational health and support

    An RMM—remote monitoring and management platform—is the operational layer. Exact features depend on the RMM product and the way an IT provider configures it, but its everyday responsibilities often include:

  • Monitoring device health, storage, performance, and alerts
  • Deploying patches or helping confirm patch status
  • Running maintenance and remediation scripts
  • Providing remote support
  • Maintaining hardware and software inventory
  • Generating service tickets and operational history
  • Identifying a recurring issue before it becomes another user complaint
  • An RMM answers:

    Is this device healthy, current, visible, and supportable today?

    Intune can perform some endpoint-management and remediation functions that overlap with an RMM. An RMM can report on conditions that matter to a compliance policy. The difference is emphasis: Intune is generally the stronger Microsoft identity, policy, and access-control layer; an RMM is generally the stronger ongoing service-operations layer.

    Where the overlap matters

    The systems should reinforce one another, not compete.

    | Overlap | Useful outcome | Decision to make |
    | ———————– | ———————————————————– | ——————————————————————————- |
    | Apple Business + Intune | Zero-touch enrollment and supervised device setup | Which MDM service receives Apple devices automatically? |
    | Intune + RMM | Security policy plus monitoring, remediation, and support | Which tool owns patching, and which one opens the ticket when it fails? |
    | Apple Business + RMM | Better asset and lifecycle context | Which system is the trusted record of company ownership? |
    | All three | A device that is known, configured, secure, and supportable | Who owns the full lifecycle when the employee leaves or the device is replaced? |

    The most common mistake is not selecting the “wrong” product. It is allowing two systems to be responsible for the same control—or assuming that one system handles a job it does not.

    For example, if Intune and the RMM both try to govern operating-system updates, the result can be conflicting timing, unclear reporting, or a support team unable to say which system failed. If Apple Business assigns a device but nobody verifies that Intune enrolled it, the company may own equipment that never entered its security baseline.

    A practical division of responsibility

    For many small and midsize organizations using Microsoft 365, a sensible model looks like this:

  • Apple Business: establish company ownership, Apple identities, app licensing, and automated enrollment.
  • Intune: apply device configuration, security standards, application controls, and Microsoft 365 access requirements.
  • RMM: monitor health, automate routine maintenance, deliver support, and preserve operational history.
  • The details will vary. A company with only a few iPhones may need a lighter model. A professional-services firm with managed Macs, remote employees, regulated information, and Microsoft 365 may need all three layers working together.

    The goal is not to collect dashboards. It is to make sure a business-owned Apple device has a clear path from purchase, to enrollment, to secure use, to support, to retirement.

    Ask about any company Mac, iPhone, or iPad:

  • Can we prove it belongs to us?
  • Can we confirm it meets our access and security requirements?
  • Can we see whether it is healthy and support the person using it?
  • Can we recover or retire it without depending on one employee’s memory?
  • If those questions have clear answers, the device is managed.

    If the answer is, “We have an Apple portal somewhere, and our IT company can probably see it,” the organization may have software—but not yet a device-management model.

    Permalink

    Assorted Links — September 14, 2026

    A cyber incident can be contained without being understood immediately

    NovoCure’s September 1 filing says a subsidiary found unauthorized access in mid-August, activated its response plan, and was still investigating exposed information. The filing says medical treatment devices were not accessed and systems remained functional. It is a useful incident-reading lesson: describe what is known, what is protected, and what remains under review.

    Hardware security is becoming a lifecycle problem

    NIST’s new workshop report describes priorities spanning chip design, manufacturing, deployment, operation, and end of life. Provenance, attestation, software bills of materials, and traceability appear together because a secure component is not enough if nobody can explain where it came from or what happened to it later.

    A data center now arrives with a public balance sheet

    Canada’s responsible-data-center principles ask projects to account for electricity ratepayers, water use, and lasting local benefits. The framework is not a universal rulebook, but it captures a practical shift: compute capacity is infrastructure with physical inputs and community consequences, not an invisible cloud abstraction.

    Digital resilience includes the things that are not called cyber

    Singapore introduced a bill covering the security and resilience of major cloud services and data centers, including power, cooling, fire, and other operational failures. It is a useful reminder for smaller organizations too: an incident plan that names malware but not dependencies is not yet a resilience plan.

    NASA’s new X-ray objects are a reminder that discovery starts as a puzzle

    NASA’s September science roundup highlights Chandra observations of mysterious X-ray objects alongside other current work. A compelling scientific result does not always arrive as an answer; sometimes it is a new object or signal that makes the next observation worth doing.

    An AI cyber-defense pilot starts with constrained work

    The Center for Internet Security announced a pilot with state and local organizations to examine whether AI can help identify, validate, and prioritize defensive findings. The interesting boundary is the work being tested: assisting established controls and remediation decisions, not handing an unattended system the authority to run security.

    AI operations still have to earn trust from the people on call

    NTT DATA says it is expanding an AI-powered infrastructure-operations platform using monitoring, predictive analytics, and automation. The vendor’s claims are not independent performance evidence, but the operational question is useful: an AI system becomes part of support only when people can see what it noticed, why it acted, and how to correct it.

    Space technology is also a story about the systems behind the mission

    NASA’s Discovery Days program uses hands-on exhibits to show how power, propulsion, communications, and materials support Artemis work. The event is aimed at the public, but the underlying idea travels well: visible products depend on layers of specialized infrastructure that usually stay out of sight.

    Permalink

    Assorted Links — September 12, 2026

    This week: the invisible work behind infrastructure, maps, measurements, and machines that refuse to be simple.

    Planning a Grid With Too Many Possibilities

    The Department of Energy says its GridFM 2.0 research project aims to help utilities evaluate up to 1 billion grid scenarios in 24 hours. Those are project goals, not achieved results. The interesting part is the bottleneck being named: infrastructure planning increasingly depends on comparing possibilities before the real-world queue gets longer.

    A Highway Corridor Is Also a Utility Corridor

    The Transportation Department’s America’s Great Corridors of Commerce initiative is seeking input on coordinating highways and rail routes with transmission, fiber, water, and other utilities. It is a useful reminder that infrastructure is rarely one thing. Right-of-way, permitting, financing, and maintenance often matter as much as the wire or pipe itself.

    A National Map Gets More Useful by Becoming Standard

    USGS released Version 2.0 of its Cooperative National Geologic Map on September 3, expanding standardized coverage to all 50 states and most U.S. territories. The quiet achievement is the shared format behind it: a national resource becomes more useful when people can compare, extend, and reuse the data.

    The Most Important Part May Be the Wiring

    NASA’s Titan-bound Dragonfly rotorcraft has received its electrical harness, carrying power and data among the vehicle’s systems. The harness does not get much credit for itself, which is precisely its charm. Plenty of critical systems are built to make other systems possible.

    Five Sensors See What One Could Not

    NASA researchers used five detectors to study a sporadic-E layer that can disrupt long-distance radio signals and found unexpected internal complexity. The result is enjoyable science and a durable measurement lesson: a clean reading from one point can describe only the point where it was taken.

    The Cold War’s Code Breaker Was a Specialized System

    IEEE Spectrum revisits the NSA’s Harvest system: a specialized high-speed processor attached to IBM’s Stretch computer. Its systems lesson is that computing performance comes from matching specialized hardware, general-purpose infrastructure, software, and people to a mission—not from the mainframe alone.

    A Digital Twin Meets the Real Airplane

    NASA’s X-59 quiet-supersonic aircraft has completed 25 test flights. Its team uses a real-time digital twin to compare flight data against simulated predictions—and so far, the aircraft’s behavior has closely matched the models. The useful engineering lesson is that a digital twin is not a decorative dashboard; its value arrives when the real world gets a chance to disagree.

    An Agent Needs Its Own Identity

    WorkOS announced Agent Auth in early access on September 2. Its stated alternative to a long-lived API key or borrowed user session is an agent identity with scoped, short-lived tokens and revocable sessions. The useful question is not whether an agent feels like an employee; it is whether the organization can say which identity made a call, for whom, and with what permission.

    Permalink

    When a Cyber Incident Reaches the Order Queue

    For a few days in late August, Boston Scientific could still take some customer orders. It could not yet process or ship them. The difference is easy to miss until it becomes the whole story.

    On August 25, 2026, the company identified a cybersecurity incident affecting certain information-technology systems. Its first SEC filing said the resulting global disruption limited access to systems and business applications supporting operations, including order processing and shipping. Two days later, the company said the outage was also affecting manufacturing and that electronic orders could be placed into a queue for future fulfillment.

    The public record does not identify the intruder, the initial access method, or a complete technical chain. It should not be read as a technical postmortem. It is, however, a useful record of something that often gets lost in cyber-incident shorthand: an unavailable business system can turn an IT problem into a physical-flow problem very quickly.

    What is confirmed

    Boston Scientific said it activated incident-response procedures and engaged outside cybersecurity experts after detecting the incident. Its August 26 filing described a global operational disruption, while stressing that the scope, nature, and financial effects were still under investigation.

    By August 27, the company said it remained in a network outage affecting certain operating systems and business applications. It said customers could continue to submit orders electronically through EDI, but that it could not then process or ship orders. The distinction matters. Demand had not vanished. The organization had preserved a way to receive requests, but not the normal path for turning those requests into delivered products.

    The same update said the disruption affected the ability to manufacture products. Boston Scientific also described limits on new remote-monitoring activations for certain cardiac devices, while reporting no impact to implantable cardiac-rhythm-management device function or to previously active remote monitoring. Those are company findings, not a basis for broader claims.

    The order queue is a recovery artifact

    An order queue is not merely a backlog. It is a compact description of a business’s dependencies. To fulfill the order, someone needs a valid request, inventory information, a location, a product that can be released, a shipping path, and a record that lets the company tell the customer what happened next. In a manufacturer, the queue may also touch production, sterilization, distribution, sales inventory, and supplier coordination.

    That is why the phrase we can still take orders can be both reassuring and incomplete. It preserves a valuable commercial and customer-support function. It also creates a recovery obligation: the queued work must later be reconciled, prioritized, fulfilled, and explained without quietly losing orders or creating a second round of confusion.

    For a 20-to-100-person organization, the equivalent might be a service ticketing system, payroll batch, patient schedule, dispatch board, purchase-order inbox, or shared spreadsheet that somehow became the only way work enters the building. The important question is not whether it has a sophisticated name. It is whether the company knows what happens to new work when the normal system is unavailable.

    Recovery is not one switch

    Boston Scientific’s later updates show why restoration has to be sequenced. On September 3, the company said it had begun restoring shipping capabilities for most products at major distribution centers and was moving orders through fulfillment as capabilities were validated. On September 5, it said its major distribution centers were processing and shipping at or above normal operating levels, sterilization facilities were operational, and manufacturing had resumed across most facilities globally. The same update said teams were still reducing backlogs and restoring remaining capabilities.

    That is a more useful picture than either “everything is down” or “we are back.” A business can regain enough capacity to accept work before it can fulfill it. It can restore shipping before every manufacturing capability is online. It can process new orders while older queued work still requires attention. Each recovery step changes which promises the organization can safely make.

    On September 8, Boston Scientific said substantial restoration had occurred but that the timeline for full operational recovery remained uncertain. It also said the incident was likely to have a material impact on its third-quarter and full-year 2026 results and that it no longer expected to meet previously issued growth and adjusted-EPS guidance. A system outage can interrupt the work around a product even when the product itself remains functional.

    What the public record does not establish

    It does not establish who was responsible, how access was obtained, whether data was taken, or whether a particular control would have prevented the disruption. Boston Scientific reported on September 8 that it had not identified evidence of ongoing unauthorized access, but its investigation remained ongoing. The company said product-quality analyses indicated no impairment to product function; that statement should not be stretched into a conclusion about every possible impact outside the scope it described.

    Those unknowns are not a weakness in the account. They are the honest boundary of an incident that is still being investigated. Good recovery planning does not wait for an attribution headline before asking which business promises depend on which systems.

    The smaller-company version

    Most organizations do not need a global recovery program to learn from this. They need a short, tested map of their work queues. Which requests may continue arriving during an outage? Where will they be recorded? Who decides priority? How will the team avoid duplicate work when systems return? Which customer-facing statements are true at each stage of recovery?

    The order queue is where cybersecurity, operations, and customer trust meet. A recovery plan that protects systems but cannot explain what happens to incoming work is incomplete. The useful goal is not to predict every incident. It is to know, before one occurs, how the organization will keep its promises honest while it rebuilds the path from request to result.

    Permalink

    When a Price Becomes a Data Flow

    A price used to look like a small fact. It sat on a shelf, in a catalog, or in a quote, and the difficult questions were mostly commercial: Is it competitive? Is it profitable? Who approved the discount?

    Now a price can be the final output of a much larger system. It may reflect inventory, location, time, a promotion, a customer segment, browsing behavior, purchase history, or data supplied by another company. The number may still fit on a price tag. The decision that produced it may not.

    In January 2025, the Federal Trade Commission published initial staff findings from an ongoing surveillance-pricing market study. The study examined how intermediaries can use personal and behavioral data in tools that influence the prices or promotions consumers see. It was not a final rule, an enforcement policy, or a finding about every retailer. It was an early look at a system that deserves clearer questions.

    The broader operational question is simple: if data helps produce a price, can the organization explain the data flow behind it?

    A price is no longer only a pricing decision

    Consider the ordinary-sounding instruction, “show a better offer to likely buyers.” That may require a customer profile, a segmentation rule, a model or rules engine, a channel where the offer appears, an experiment log, and a decision about whether the customer sees the same offer elsewhere. It may also require information from a retailer, an advertising platform, a loyalty system, or a third-party data provider.

    At that point, pricing has become a workflow. And workflows need owners.

    The FTC’s initial staff perspective described inputs such as location, demographics, browsing patterns, shopping history, and interactions such as mouse movements. The study did not establish that every retailer uses every input, nor does it convert every variable price into misconduct. It does make one management problem harder to ignore: a business can create a consequential customer-facing decision without anyone being responsible for the whole chain.

    The three questions behind the number

    First: what data enters the pricing decision? A location used to estimate delivery cost is not the same thing as a browsing history used to infer willingness to pay. An organization should be able to name its inputs and their sources without relying on the phrase “the platform does that.”

    Second: what rule turns those inputs into an offer? The rule may be a simple promotion table, a vendor feature, or a more complicated model. The important distinction is not whether it feels technical. It is whether someone can describe the purpose, limits, and exceptions well enough to test the result and answer a reasonable customer question.

    Third: who can explain the outcome? Marketing may own the campaign. Sales may own the discount authority. Finance may own margins. IT may manage the systems and integrations. Privacy or legal may review the data use. If nobody owns the explanation across those boundaries, the organization has not merely delegated a task; it has delegated accountability into a hallway.

    Transparency is an operations requirement

    People sometimes hear “transparency” as a copywriting project: add a sentence to a policy page and continue enjoying lunch. But a disclosure can be accurate only if the underlying process is understood. A customer-facing explanation depends on records of what data was used, what vendor or system processed it, what version of a rule applied, and who approved the program.

    That is not an argument for documenting every routine price adjustment like a space launch. It is an argument for matching documentation to consequence. A standard wholesale price list needs ordinary controls. A system that changes an individual customer’s offer based on personal information deserves a clearer inventory, an accountable owner, a review path, and a way to investigate an unexpected result.

    Start before the pricing tool arrives

    The useful preparation is not a grand policy that tries to forecast every algorithm. It is a short working map. List the pricing and offer systems already in use. Identify what customer or behavioral information enters each one. Record which team owns the business purpose, which team owns the technical connection, and who can approve an exception. Then ask a practical test question: if a customer asks why this offer appeared, can we give a truthful explanation without reverse-engineering our own process?

    The FTC’s study remains ongoing, and its initial findings should not be described as a final rule or universal finding about retailers. Its value as an operational prompt is available now. When a price becomes a data flow, the number is only the visible part of the decision. The organization still has to own the rest of it.

    Permalink

    The Factory Bottleneck Is Often a Data Bottleneck

    A jet engine is a collection of impressive objects: fan blades, turbine blades, sensors, fuel systems, and metal parts expected to perform in conditions most office equipment would regard as personal.

    It is tempting to think the constraint is the engine itself.

    Today’s aerospace news points somewhere else. Reuters reports that GE Aerospace is buying Consolidated Precision Products, a manufacturer of critical metallic engine components, for $12 billion. The purpose is to help secure capacity for precision castings—parts that sit deep inside an engine and have become a stubborn production bottleneck. Reuters’ account of the transaction describes the deal as part of a longer effort to make aerospace production more reliable.

    The interesting question is not merely why GE wants to own more of its supply chain. It is why an organization capable of designing some of the world’s most advanced machinery would spend that much to gain more control over a process that begins with liquid metal.

    The answer is that capacity is not a machine count.

    A casting must become a part that meets exact requirements for shape, strength, heat resistance, and internal integrity. Doing that consistently requires equipment, materials, process controls, inspection, trained people, and a great deal of accumulated knowledge.

    It also requires information to arrive in the right place, in the right form, at the right time.

    The machine is only one part of the production system

    A factory can have a machine, an order, and a shortage at the same time.

    The missing ingredient may be a current drawing. It may be a material certification. It may be a quality record that cannot be located, an engineering change that did not reach the floor, a supplier update trapped in email, or an approval that belongs to someone who is unavailable.

    None of those problems looks like a manufacturing bottleneck at first. They look administrative.

    But production does not experience them as administrative. Production experiences them as waiting.

    This is where IT becomes part of manufacturing capacity. Not as a separate department that keeps printers working, but as the system that allows a complicated organization to know what it is making, which version is correct, what changed, what passed inspection, who owns the next decision, and what must happen before work can continue.

    A manufacturer does not need every system to be fashionable. It needs the critical systems to be dependable and connected enough that people are not rebuilding the truth from spreadsheets, inboxes, paper travelers, and memory.

    Data quality is a production issue

    Manufacturers sometimes talk about data as though it belongs to finance, IT, or the people who enjoy dashboards.

    But the data that matters on a production floor is not abstract. It is operational:

  • Which revision of the drawing is approved?
  • Which material lot went into this job?
  • Which inspection results belong to this serial number?
  • Has the customer approved the deviation?
  • Which supplier promised which delivery date?
  • Who can decide whether the job proceeds, stops, or changes?
  • A wrong answer can create rework. No answer can create a queue.

    That is the quiet connection between information systems and physical output. Good data does not make a turbine blade. It makes it possible for the right people to make the right turbine blade, prove what happened to it, and respond when something changes.

    The same principle applies well beyond aerospace. An automotive supplier may need traceability for a part run. A defense contractor may need to show that controlled information was handled through an approved process. A medical-device manufacturer may need records that connect a batch, a test result, and a release decision.

    In each case, the product is physical. The ability to produce it reliably depends on a chain of information.

    The real test is what happens when something changes

    Most systems look adequate when the work is routine.

    The test comes when an engineer changes a specification, a supplier misses a date, an inspection fails, a customer asks for an exception, or a key person is out for a week. Can the organization identify the affected work? Can it notify the right people? Can someone authorize the next step? Can it later explain why that decision was made?

    If the answer depends on finding the one person who “knows how we do this,” the process may be functioning. It is not yet resilient.

    That is why the most valuable IT work in a manufacturing business is often unglamorous: organizing documentation, securing access without blocking the floor, improving system integration, protecting the records that prove quality, and making ownership visible when an exception occurs.

    The goal is not to turn every plant into a software project. It is to make sure the information surrounding the work is as reliable as the work itself needs to be.

    GE’s acquisition will not make precision casting simple. It is evidence that difficult capacity is worth bringing closer to the center of the business.

    For manufacturers, the practical lesson is smaller and more immediate: when output is constrained, do not inspect only the machines. Follow the data, the approvals, and the handoffs around them. The bottleneck may be waiting in an inbox.

    **Source:** Reuters, “GE Aerospace bets on ‘black art’ of castings to secure jet engine supply”.

    Permalink

    An AI Policy Starts With Data Handling

    An AI policy often begins with a list of names. ChatGPT: yes or no. Copilot: yes or no. Some other tool with an unusually cheerful gradient: perhaps, pending a meeting.

    The list feels concrete because it has logos on it. It is also the part most likely to age badly. Products change, features change, contracts change, and the same model can be harmless in one workflow and consequential in another.

    The better opening question is not Which AI tool is allowed? It is What is this workflow allowed to receive, produce, decide, and leave behind?

    That shift matters because the useful unit of governance is not the model or the vendor. It is the workflow: the specific path through which information enters, is processed, becomes an output, and sometimes turns into a business action.

    1. What data may enter this workflow?

    “Can we use AI for this?” is usually shorthand for a more precise question: may this particular information enter this particular workflow?

    A generic event invitation is not a customer contract. A public product description is not a spreadsheet of employee compensation. A list of meeting topics is not a support ticket history. Good policy gives people a usable way to recognize those differences: public information, ordinary internal work, confidential business material, regulated data, and information governed by a customer or partner commitment.

    The important detail is not merely whether a provider says it has strong security. It is whether the proposed use fits the organization’s rules for that kind of information. NIST’s Privacy Framework is useful here because it treats privacy as enterprise risk management and includes the data-processing ecosystem: the other entities, services, and relationships involved when information moves through a business process.

    Start by writing down the permitted inputs for each approved workflow. A marketing brainstorming assistant may accept public material and approved internal copy. A workflow intended to summarize a customer record may require an entirely different review. The point is not to produce a classification taxonomy so grand that no one uses it. It is to prevent a familiar shortcut from becoming an unexamined data route.

    2. What may the workflow produce or decide without human review?

    AI systems can draft, sort, summarize, recommend, route, and increasingly initiate actions. Those verbs deserve different rules.

    A draft may be useful precisely because a person will revise it. A recommendation may be useful because a person will weigh it against context the system cannot see. A message to a customer, a change to a record, a purchasing decision, a security response, or an employment-related decision deserves a more deliberate boundary.

    One practical policy question is: What is the last point at which a person must review this before it changes the organization’s position? The answer may vary by workflow. A tool may create a first-pass meeting summary without a formal gate. It should not quietly send a customer commitment, alter a system of record, or decide an exception because its prose sounds confident.

    NIST’s generative-AI profile and AI Risk Management Framework both emphasize that organizations must adapt risk management to their own context and risk tolerance. That is not an invitation to vague caution. It is a reason to name the decision boundary clearly enough that an employee knows when an assistant is helping and when it is substituting for accountable judgment.

    3. What new record, retention, and customer-commitment obligations does it create?

    Every new workflow has an afterlife. It may create prompts, uploads, logs, generated files, audit records, drafts, and copies in connected business systems. It may also create a promise—explicit or implied—about how customer information is handled, how long it remains available, or what happens when someone asks for it to be corrected or removed.

    People often ask one narrow question: whether a model trains on their data. That can matter, but it is not the whole record question. The broader question is: if this interaction matters six months from now, where is the record, who can retrieve it, what retention rule applies, and what agreement governs it?

    This is where a policy becomes operational rather than decorative. Before approving a workflow, identify its record owners and its retention setting. Check whether it changes a customer commitment. Decide whether the output needs to be preserved, reviewed, or routinely deleted. An organization does not need a committee for every prompt; it does need someone able to answer these questions for the workflows that matter.

    One brief example

    A connected application can be a useful illustration, but it is not the center of the story. If a workflow reads a project folder and produces a summary, the policy questions are still the same: what files may enter, whether anyone checks the summary before it is used, and what new copy or record exists afterward. The connection is simply where those decisions become visible.

    Tool lists will keep changing. The three questions will not. They give an organization a way to evaluate the next product without pretending that a logo is a governance model.

    Permalink